Robots.txt: The File That Search Engines Read First | SEO Tricks
Before a search engine explores your site, there is a small text file waiting at the door.
Quick Summary Box
Robots.txt is a simple text file that tells web crawlers which parts of a website they may or may not crawl. It is primarily a crawling directive, not a command for indexing or ranking.
A valid
robots.txtshould be available at the site root and return the instructions intended for crawlers. For a real SEO check, it is not enough to know that the file exists: its content and the way it is generated must also be correct.
The Question
A robots.txt file looks almost too simple to matter.
One small text file, one familiar URL:
https://example.com/robots.txt
But what exactly is it supposed to do?
Does it tell search engines which pages to index?
Does it affect rankings?
Does it simply give crawlers directions before they explore the site?
And, perhaps most importantly:
What should we actually expect to find when we open a website’s robots.txt?
That is the question behind this SEO check.
Why It Matters
Search engines need to crawl websites efficiently. A robots.txt file provides a standard place at the root of a site for publishing crawling instructions.
But several SEO concepts are easy to mix up.
Crawling is not the same as indexing.
Indexing is not the same as ranking.
A robots.txt file primarily concerns crawling: it tells crawlers which areas they may access and which they should avoid.
That makes the file part of a website’s technical SEO infrastructure. If it is missing, inaccessible, malformed, or contains unintended instructions, crawlers may not receive the directions the site owner intended.
And there is another important lesson:
Finding a robots.txt file is not the end of the check.
We also need to look at what the file actually contains — and, for a generated website, how that content got there in the first place.
The Check
We started with the most basic check:
Does the site actually have a robots.txt file?
The live URL told us the answer immediately:
https://pivtorak.studio/robots.txt → 404 File not found
So before checking directives, crawling rules, or sitemap compatibility, we had to find out why the file was missing.
We then traced how the site was built and how Hugo could generate robots.txt.
First, we checked the Hugo configuration for the setting responsible for generating the file:
enableRobotsTXT = trueNext, we looked for an explicit robots.txt template in the project and in the theme:
layouts/robots.txt
themes/hugo-book/layouts/robots.txt
We also checked whether a static file already existed:
static/robots.txtNone of these locations contained a robots.txt source file.
We then examined the Hugo theme’s text templates and the available output formats to understand what Hugo could use when generating a plain-text robots.txt.
Finally, instead of deploying an unverified change, we ran a local Hugo build and inspected the generated output:
E:\GitHubProjects\pivtorak.studio.github.io\public\robots.txtThis gave us a controlled way to answer the next question:
Could Hugo generate the missing file correctly before we changed the live site?
Verification
This is where the investigation changed direction.
The local build confirmed that Hugo could generate a robots.txt file — but the generated file was not a valid robots.txt for our site.
We therefore stopped before committing or deploying anything.
Source → Build
The source configuration contained:
enableRobotsTXT = trueAfter the build, Hugo created:
E:\GitHubProjects\pivtorak.studio.github.io\public\robots.txtSo at first glance, the problem appeared to be solved.
But opening the generated file revealed something very different from the expected robots directives.
Instead of a small plain-text file such as:
User-agent: *
Allow: /

Sitemap: https://pivtorak.studio/sitemap.xml
the generated file was approximately 34 KB and began with:
Pivtorak.Studio
- ...
It then continued with a long list of the site’s pages and URLs.
That content was clearly not a set of crawler instructions.
The file was effectively a text representation of the site’s content, not a functional robots.txt.
Why this was a problem
A robots.txt file needs to communicate crawling rules through robots directives such as User-agent, Allow, Disallow, and, where appropriate, a Sitemap reference.
Our generated file did not do that.
So although:
a file existed,
we could not conclude that:
the robots.txt worked.
This distinction was critical.
The build had successfully produced a file at the expected path, but the content of that file was wrong.
Therefore, the correct verification result at this stage was:
Source
   ↓
enableRobotsTXT = true
   ↓
Build
   ↓
robots.txt exists
   ↓
Content is incorrect
   ↓
STOP
We had not reached the Live stage, and there was no reason to commit or deploy an unverified result.
The next step was therefore not deployment.
It was to find out why Hugo had generated this particular content and which template had produced it.
Final Takeaway
A robots.txt check should begin with a simple question:
Does the file exist, and does it contain the instructions it is supposed to contain?
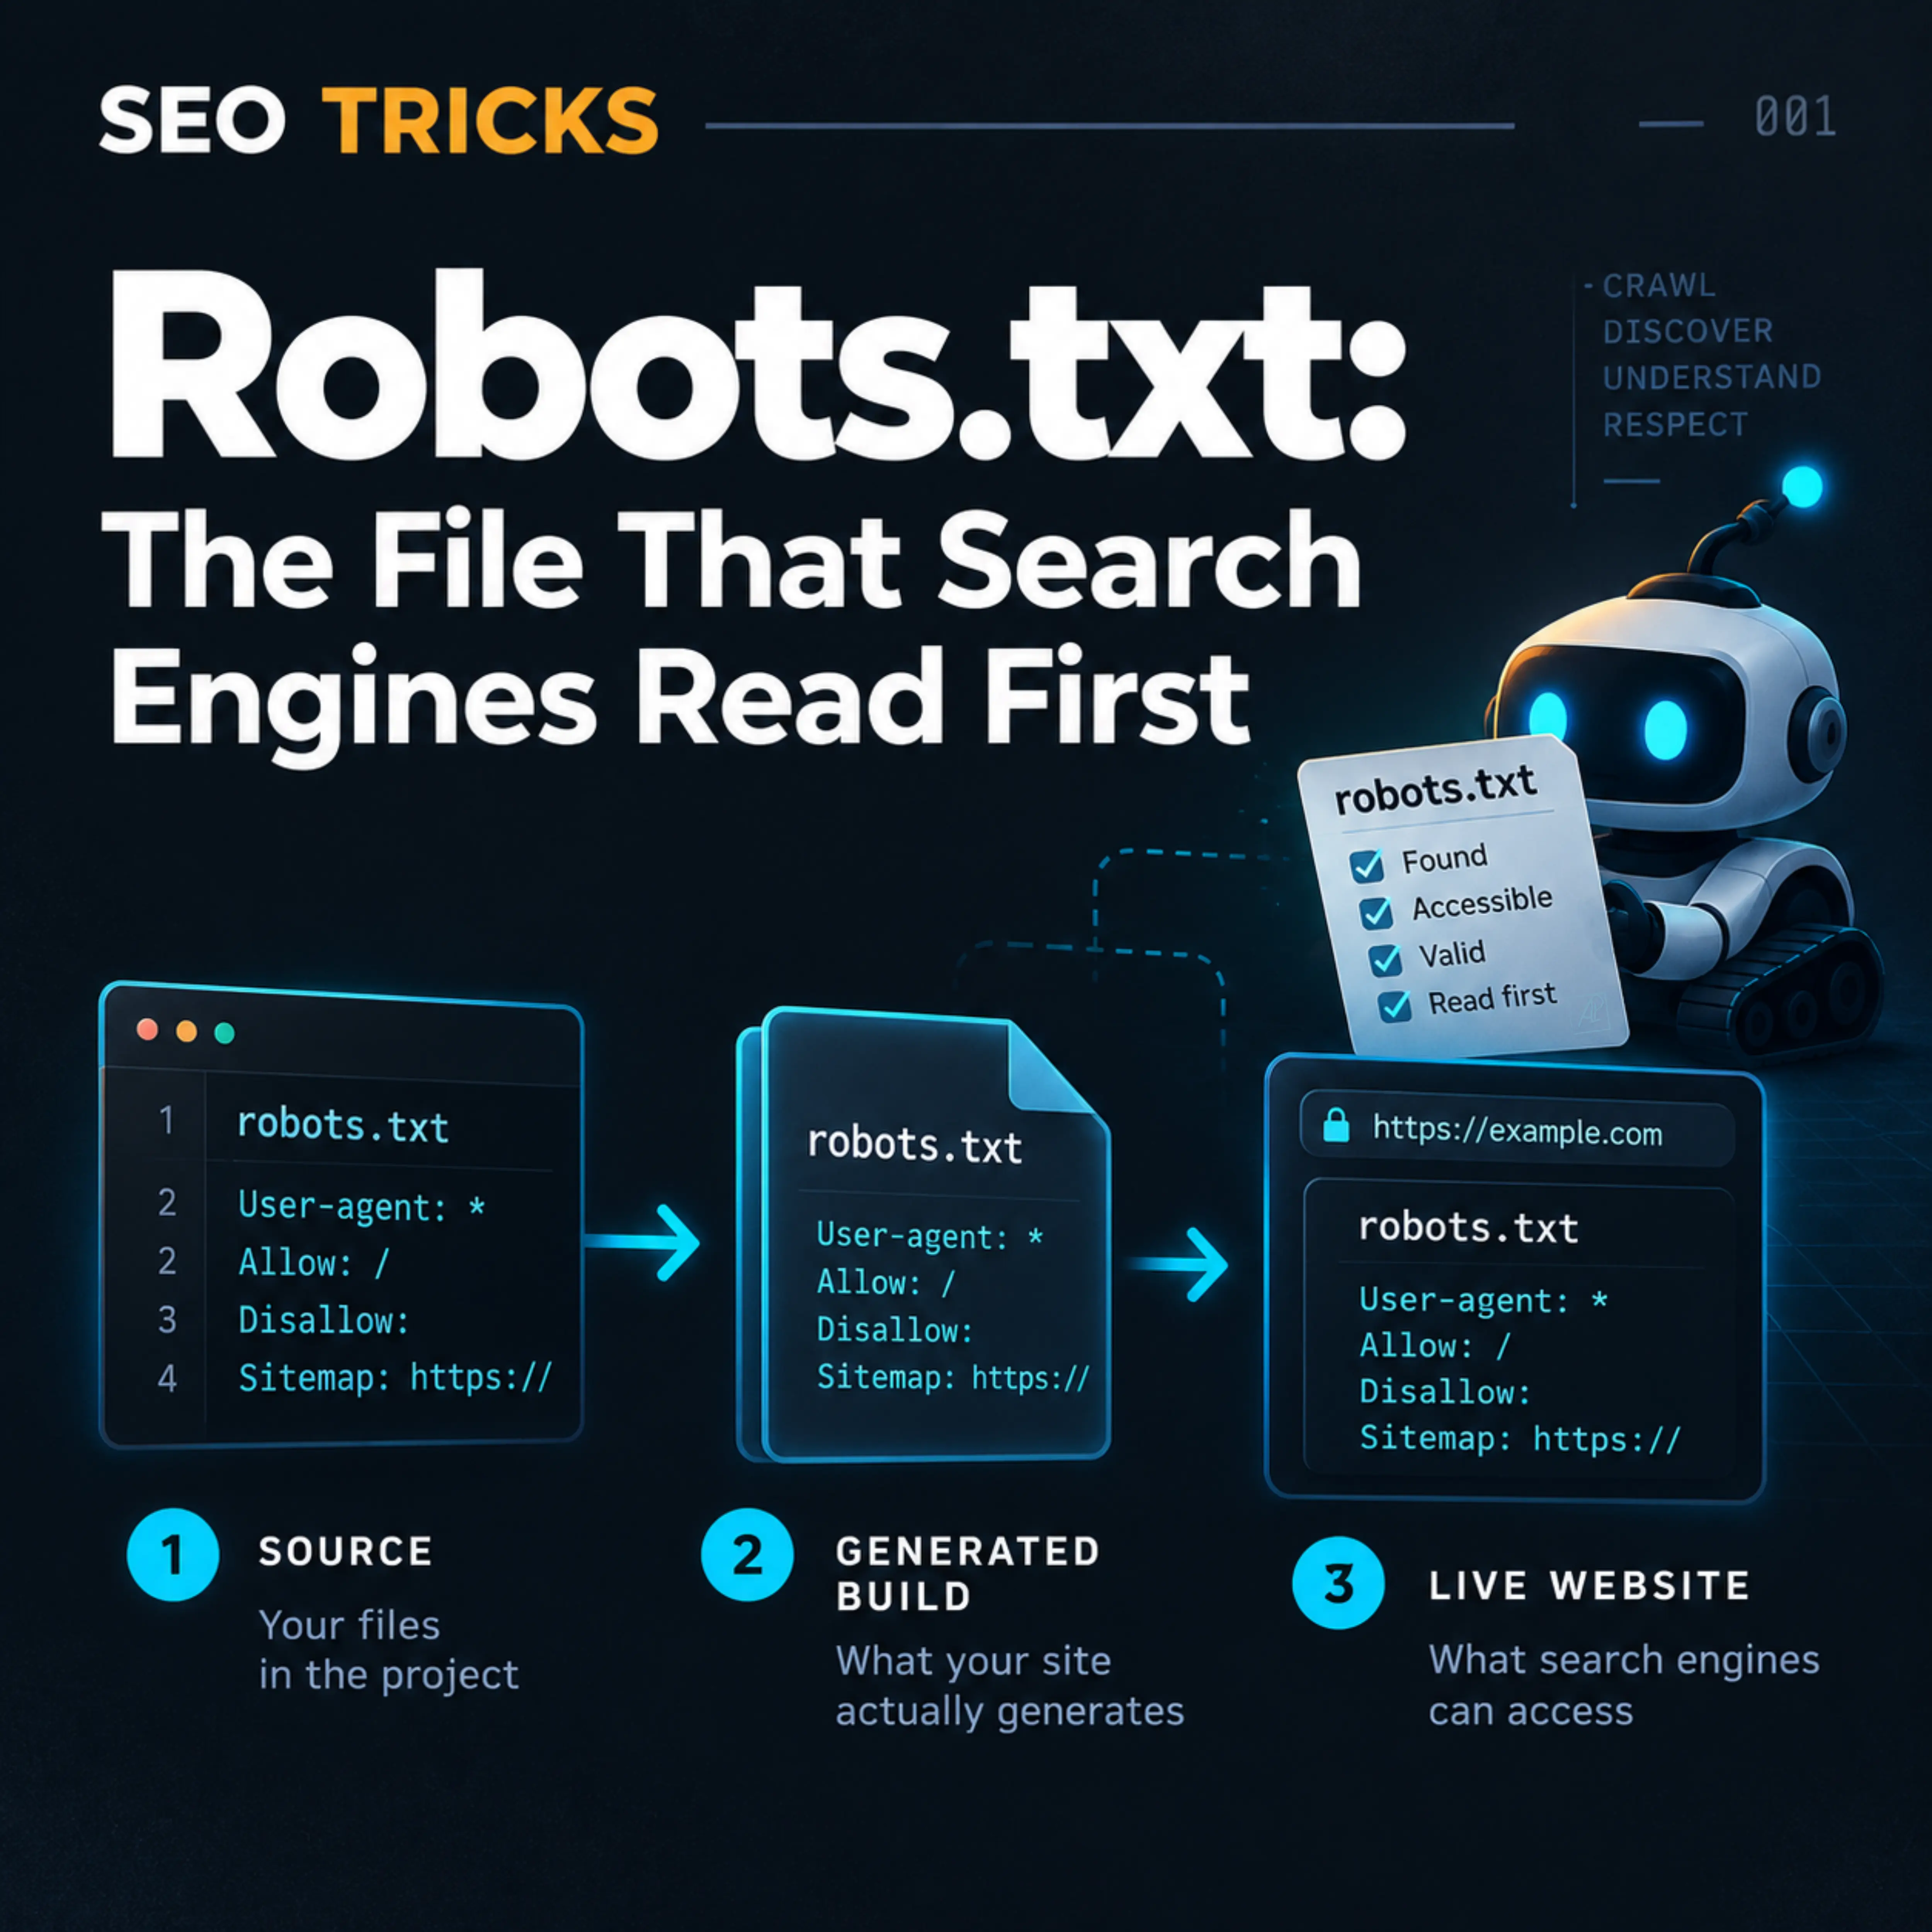
For a generated website, the safest approach is to verify it at three levels:
Source → Generated Build → Live
The source tells us what we asked the system to do.
The build tells us what the system actually generated.
The live site tells us what search-engine crawlers can actually receive.
A file appearing in the build is not enough. And a file existing at the expected URL is not enough either.
Check the file. Then check what is inside it.
Sometimes the smallest SEO file deserves a three-level check.
robots.txt · technical SEO · crawling · crawl budget · sitemap
Alt-text:
Three-level robots.txt verification diagram showing Source, Generated Build, and Live website checks.
SEO Tricks. Robots.txt: The File That Search Engines Read First. AP | Pivtorak.Studio. 07.09.2026
© Anna Pivtorak (Kostyuk)